Category: Technology

  • How Quantum Computing Algorithms Work: A Beginner’s Guide

    How Quantum Computing Algorithms Work: A Beginner’s Guide

    Explore the fascinating world of quantum computing algorithms, their workings, and applications in this comprehensive beginner’s guide.

    Understanding Quantum Computing Algorithms

    Quantum computing algorithms are a set of instructions designed to run on quantum computers. They differ fundamentally from classical algorithms, which rely on classical bits as the basic unit of information. In quantum computing, we work with quantum bits, or qubits, which can exist in multiple states simultaneously thanks to the principles of superposition. This characteristic allows quantum computers to process information in ways that traditional computers simply cannot match.

    That said, “process information” is easy to oversell. A quantum computer doesn’t magically evaluate every possibility and hand you the best one. Instead, you build a quantum state where wrong answers interfere destructively and right answers interfere constructively, and then you measure. If you didn’t shape that interference correctly, you just get noise (or an answer that’s right only some percentage of the time).

    How Quantum Computing Algorithms Work: A Beginner’s Guide

    At the heart of quantum computing is the interaction of qubits through specific algorithms. One of the most notable aspects of quantum algorithms is their ability to handle exponentially larger datasets than classical algorithms can. For example, Shor’s algorithm, a prominent quantum algorithm, can factor large numbers much more efficiently than classical methods, which is significant for cryptography. Here’s a brief overview of how quantum computing algorithms work:

    1. Superposition: This principle allows qubits to be in a state of 0, 1, or both at the same time. It enables quantum algorithms to process numerous possibilities simultaneously.

    2. Entanglement: When qubits become entangled, the state of one qubit can depend on the state of another, no matter how far apart they are. This interdependence is a crucial feature that enhances computational power in quantum systems.

    3. Quantum Gates: Similar to classical logic gates, quantum gates manipulate the state of qubits. They perform operations such as rotations and flips, allowing quantum algorithms to explore complex computational paths.

    To make those less abstract, imagine you’re writing a program where the “data” is a vector, and every gate is a matrix multiplication. That’s basically it. The weirdness comes from two rules:

    • You’re not allowed to copy an unknown quantum state (no-cloning), so you can’t just “duplicate a variable.”
    • If you measure halfway through “to see what’s going on,” you collapse the state and change the computation.

    So, a quantum algorithm often looks like: prepare an initial state → apply a circuit of gates → measure → repeat many times → do statistics on outcomes.

    Quantum Algorithms for Beginners

    For beginners, understanding specific algorithms can help demystify quantum computing. Here are some of the most significant quantum algorithms:

    • Shor’s Algorithm: Used for integer factorization, this algorithm can potentially break current cryptographic systems based on factorization problems.
    • Grover’s Algorithm: This algorithm searches unsorted databases with quadratic speedup over classical counterparts, showcasing the efficiency of quantum computing in search problems.
    • Quantum Approximate Optimization Algorithm (QAOA): This algorithm is designed for combinatorial optimization problems and is an example of how quantum computers can solve practical problems more efficiently than classical methods.

    If you’re trying to decide what to study first, I’d do it in this order: Grover (simpler mental model), then QAOA (because NISQ-era hardware can actually run small instances), then Shor (because it’s a masterpiece but has more moving parts).

    Also, one practical note: beginners sometimes assume “quantum advantage” means “always faster.” It doesn’t. Each of these algorithms has a very specific problem shape where the speedup shows up, and outside that shape you may get no benefit—or you may get a slower, noisier solution.

    Quantum Computing Algorithms Explained

    Quantum computing algorithms exhibit several advantages over classical algorithms. They excel particularly in solving complex problems related to optimization, cryptography, and materials science. For example, in drug discovery, quantum algorithms can simulate the behavior of molecules to predict their reactions, potentially leading to the development of new medications faster than traditional methods.

    Additionally, quantum algorithms can tackle problems that are intractable for classical computers. As research progresses, we are witnessing advancements in quantum computing platforms and algorithms, with companies like IBM, Google, and startups innovating in this space.

    Here’s the nuance I wish more articles spelled out: quantum algorithms typically don’t “compute an answer” the way classical algorithms do. They manipulate amplitudes. The outcome is probabilistic, so you care about the distribution of measurement results.

    A quick, real-feeling example: I once built a toy Grover search demo and expected a single run to pop out the target every time. Nope. You run the circuit many times (shots), and if you chose the right number of Grover iterations, the target shows up most of the time—not all the time. That’s not a bug. That’s the contract.

    What a quantum circuit really is

    A useful model: treat a quantum algorithm as a circuit made of three layers.

    • State prep: you start with
      (|0rangle^{otimes n}) and push it into something more interesting (often a uniform superposition).
    • Compute / mix: you apply gates that encode the problem structure—an “oracle,” a phase kickback, a mixer, a Fourier transform, whatever fits.
    • Readout: you measure, then post-process the bitstrings classically.

    Because measurement is destructive, you plan for that. You decide ahead of time what you want to measure, and you build the circuit so that measurement has a good chance of revealing it.

    Also, you don’t need to memorize matrices day one, but you should internalize that most gates are rotations on a Bloch sphere. That’s why people talk about angles, phases, and interference so much.

    Superposition is not “parallel universes”

    Superposition gets explained as “doing all computations at once.” That metaphor causes trouble. What you really have is a weighted combination of basis states.

    If you put one qubit into superposition, you get something like:

    • (|psirangle = alpha|0rangle + beta|1rangle)

    Then you apply gates that change (alpha) and (beta) (including their phases). The power comes from the fact that amplitudes can cancel. So, while it can feel like parallelism, the speedup comes from interference patterns you engineer.

    A concrete way to think about it: superposition gives you a canvas with many basis states “lit up.” The algorithm’s job is to dim the wrong ones and brighten the right ones without looking directly.

    Entanglement is a correlation you can’t fake

    Entanglement is where beginners either get mystical or dismissive. Keep it boring: it’s a joint state that can’t be factored into independent qubits.

    Why it matters for algorithms: entanglement lets you represent correlations compactly, and it enables tricks like phase kickback (where the phase of one register depends on the value of another). That’s a workhorse technique in Shor-style algorithms.

    One caution, though: entanglement is also where hardware pain shows up. Two-qubit gates are typically noisier than single-qubit gates, and deep circuits get wrecked fast on today’s devices. So, algorithm designers spend a lot of time reducing two-qubit gate count, even if the math looks elegant on paper.

    Quantum gates: think geometry, not logic

    Classical gates feel like logic: AND, OR, XOR. Quantum gates feel like geometry: rotations, reflections, phase shifts.

    • Hadamard (H) spreads amplitude evenly (great for state prep).
    • Phase gates (S, T, Rz) tweak relative phase (this is how you “steer” interference).
    • CNOT / CZ create entanglement and conditional changes.

    If you’ve ever optimized a slow piece of code, this will resonate: the gates you pick determine whether the algorithm is feasible on real hardware. Two circuits can implement the same unitary, yet one runs with 10× fewer error-prone operations.

    Shor’s algorithm: why cryptographers care

    Shor’s algorithm is famous because it factors integers in polynomial time (on an ideal fault-tolerant quantum computer). The factoring part is the headline, but the real engine is period finding.

    In plain terms:

    • You turn factoring into “find the period of a function” (number theory trick).
    • You build a quantum circuit that encodes that function.
    • You use a Quantum Fourier Transform to extract the period.

    That Fourier transform step is where interference does real work. It concentrates probability mass on measurement outcomes that reveal the period.

    Tradeoff: Shor is deep. On noisy devices, it’s mostly a teaching demo today. But it’s still the north star for why post-quantum cryptography exists.

    Grover’s algorithm: the speedup you can explain on a napkin

    Grover’s algorithm searches an unstructured space of size (N) in about (sqrt{N}) queries. The trick is amplitude amplification:

    • Start in a uniform superposition.
    • Flip the phase of the “marked” state (oracle).
    • Reflect around the average amplitude.
    • Repeat a tuned number of times.

    That reflection step is basically “push probability toward the marked state.”

    Real-world caveat: Grover doesn’t speed up everything. It speeds up problems that truly look like brute-force search with an oracle. If you already have structure (like sorting, indexes, heuristics), classical methods can be extremely competitive.

    QAOA: practical, messy, and worth knowing

    QAOA matters because it’s designed for near-term hardware. You alternate two kinds of operations:

    • A cost Hamiltonian that encodes the objective (penalize bad solutions).
    • A mixer Hamiltonian that explores the space.

    You do this for (p) layers, then you measure and use a classical optimizer to tune the angles.

    This hybrid loop is where real engineering shows up. A few pain points I’ve seen:

    • Classical optimizers get stuck because the landscape can be flat (“barren plateaus”).
    • Noise makes gradients unreliable.
    • The best parameter initialization often comes from problem-specific heuristics, not theory.

    Still, if you want to connect quantum algorithms to actual business-ish problems (routing, scheduling, portfolio constraints), QAOA is the bridge.

    Real-World Applications of Quantum Computing Algorithms

    Quantum computing applications are vast and varied. They range from cryptography (where quantum-safe encryption methods are developed) to optimization problems in logistics and finance. Here are a few notable real-world use cases:

    • Cryptography: With algorithms such as Shor’s making traditional encryption vulnerable, researchers are developing quantum-safe encryption techniques to secure data against future quantum attacks.
    • Drug Development: Companies are using quantum algorithms to model complex molecular structures, which can accelerate the discovery of new drugs.
    • Supply Chain Optimization: Quantum computing can significantly enhance logistical operations by optimizing routes and inventory management, providing businesses with a competitive advantage.

    The honest version: most “applications” today are pilots, proofs of concept, or research collaborations. That’s not a knock—it’s just where the hardware is.

    Where I do see consistent value already is in:

    • Better modeling workflows: even when quantum doesn’t win yet, teams tighten their classical baselines, clean up data, and formalize objectives. That progress sticks.
    • Chemistry and materials research: quantum systems are a natural fit for quantum simulation, even if large-scale usefulness still needs better devices.

    Cryptography: the realistic risk window

    People hear “Shor breaks RSA” and assume doom tomorrow. The timing depends on fault-tolerant quantum computers, error correction, and scale.

    Still, there’s a practical reason security folks act early: data can be harvested now and decrypted later (“store now, decrypt later”). So, if you have long-lived secrets—health data, government records, trade secrets—you migrate earlier.

    If you’re curious how organizations plan this, IBM’s roadmap style materials are a decent snapshot of how the industry thinks about timelines and milestones (even if you should read them skeptically): (IBM Roadmap).

    Drug discovery: why simulation matters

    Chemistry is where quantum computing feels least like a parlor trick. Molecules are quantum systems, and classical simulation scales badly as systems grow.

    In practice, what teams do today is smaller-scale simulation, benchmarking, and method development: which ansatz works, how to reduce noise impact, how to map molecular Hamiltonians efficiently.

    Even incremental improvements can matter because wet-lab work is expensive. If a simulation filters out a chunk of dead-end candidates earlier, that’s money and time saved.

    Logistics and finance: optimization with constraints

    Optimization is seductive because everything looks like an optimization problem. The trap is that “looks like” doesn’t mean “maps cleanly.”

    To use QAOA (or annealing-style approaches), you often need to convert constraints into penalties. That’s doable, but tuning penalty weights can be finicky. Too small, and you violate constraints. Too big, and the landscape becomes hard to search.

    A story I’ve seen: a team tries to encode a real portfolio problem with 30+ constraints, then wonders why the circuit balloons and results get noisy. The fix wasn’t “more qubits.” It was simplifying the model, picking constraints that actually move the needle, and validating against a strong classical solver first.

    Quantum Computing Algorithms Examples

    To elucidate the power of quantum computing algorithms, consider the following reported achievements:

    1. Drug Discovery: Researchers at Aalto University utilized a quantum algorithm to simulate complex materials and chemical reactions, which could lead to more efficient drug discovery processes (Science Daily).
    2. Cryptography Solutions: A new quantum encryption method was developed to enhance cybersecurity, providing robust protections against potential quantum threats in the future (Quantum Computing Report).
    3. Optimization in Finance: Financial institutions are adopting quantum algorithms to optimize portfolio management and risk assessment, showcasing practical applications of quantum computing in critical industries.1

    When you read examples like these, I’d recommend one habit: separate algorithmic progress from hardware progress.

    • If an article says “a quantum algorithm simulated X,” check the system size, error mitigation used, and whether it beat a classical method or just matched it.
    • If a vendor claims “quantum encryption,” ask whether it’s quantum key distribution (QKD), post-quantum cryptography (PQC), or something else. Those are different tools with different deployment realities.

    None of this is meant to be cynical. It’s just how you avoid getting whiplash from headlines.

    Resources for Learning Quantum Computing Algorithms

    When diving deeper into quantum algorithms, several resources can facilitate your learning. Whether you are looking for textbooks, online courses, or tools to implement your knowledge, the following resources are invaluable:

    1. Books: Consider titles such as Quantum Computation and Quantum Information by Nielsen and Chuang, which is a classic in the field.
    2. Online Courses: Platforms like Coursera and edX offer courses on quantum computing that range from beginner to advanced levels.
    3. PDF Resources: Many institutions publish free papers and guides. For example, a comprehensive guide to quantum algorithms is available in PDF format from various educational institutions (IBM Roadmap).

    If you want a practical learning path (the one I use when mentoring juniors), do this:

    Build your “minimum circuit” toolbox

    Start with a tiny set of gates and patterns, and actually run them in a simulator.

    • Make a Bell pair and measure correlations.
    • Build a 2-qubit Grover search.
    • Implement a simple QAOA layer for MaxCut on a 4-node graph.

    You’ll learn faster because you’ll hit the real questions immediately: What does measurement output look like? How many shots do I need? Why does my histogram change when I add noise?

    Read papers, but keep a scoreboard

    Reading lists are great, but you need a filter. Keep a little scoreboard in a notebook:

    • problem type
    • qubit count
    • circuit depth / two-qubit gates
    • simulator vs hardware
    • baseline comparison

    That single habit stops “paper fatigue,” since you can see patterns in what’s improving.

    A curated place to find what people are excited about right now is PennyLane’s seasonal roundups: Top quantum algorithms papers — Winter 2026 edition.

    Use one solid reference guide

    When you hit a term like “oracle,” “phase kickback,” or “Trotterization,” you want one page you trust. This guide is broad and beginner-friendly, so it’s handy as a second opinion while you’re learning: What Is a Quantum Algorithm? Complete 2026 Guide.

    In conclusion, understanding quantum computing algorithms opens up a world of possibilities in technology and other fields. As these algorithms mature, they promise to revolutionize the way we solve problems that are currently beyond our reach. Keep exploring, and you’ll be ready to engage with this exciting frontier of technology!

    Top quantum algorithms papers — Winter 2026 edition
    What Is a Quantum Algorithm? Complete 2026 Guide
  • How AI Will Change Our Lives in 2026

    How AI Will Change Our Lives in 2026

    Explore how AI will change our lives by 2026, its applications, and benefits across various domains.

    Featured image for How AI Will Change Our Lives in 2026

    How AI Will Change Our Lives in 2026

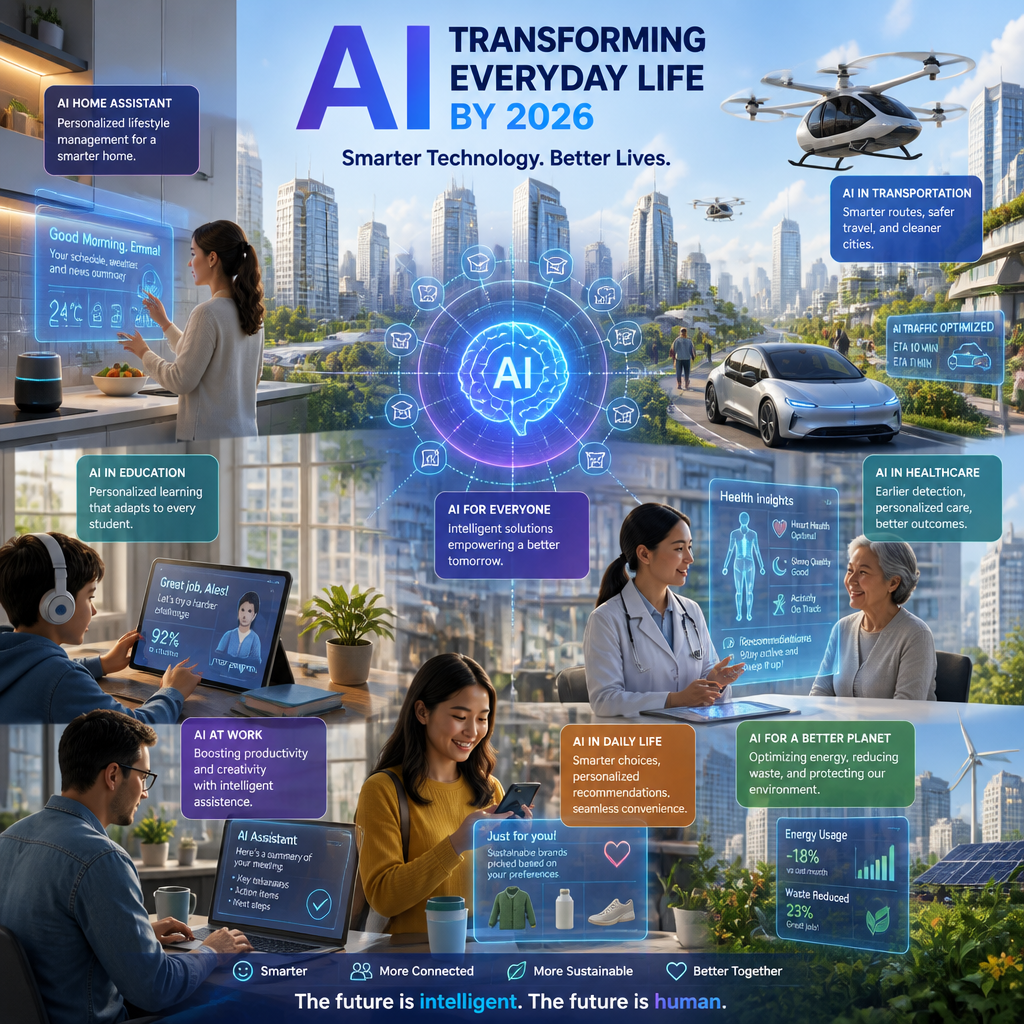
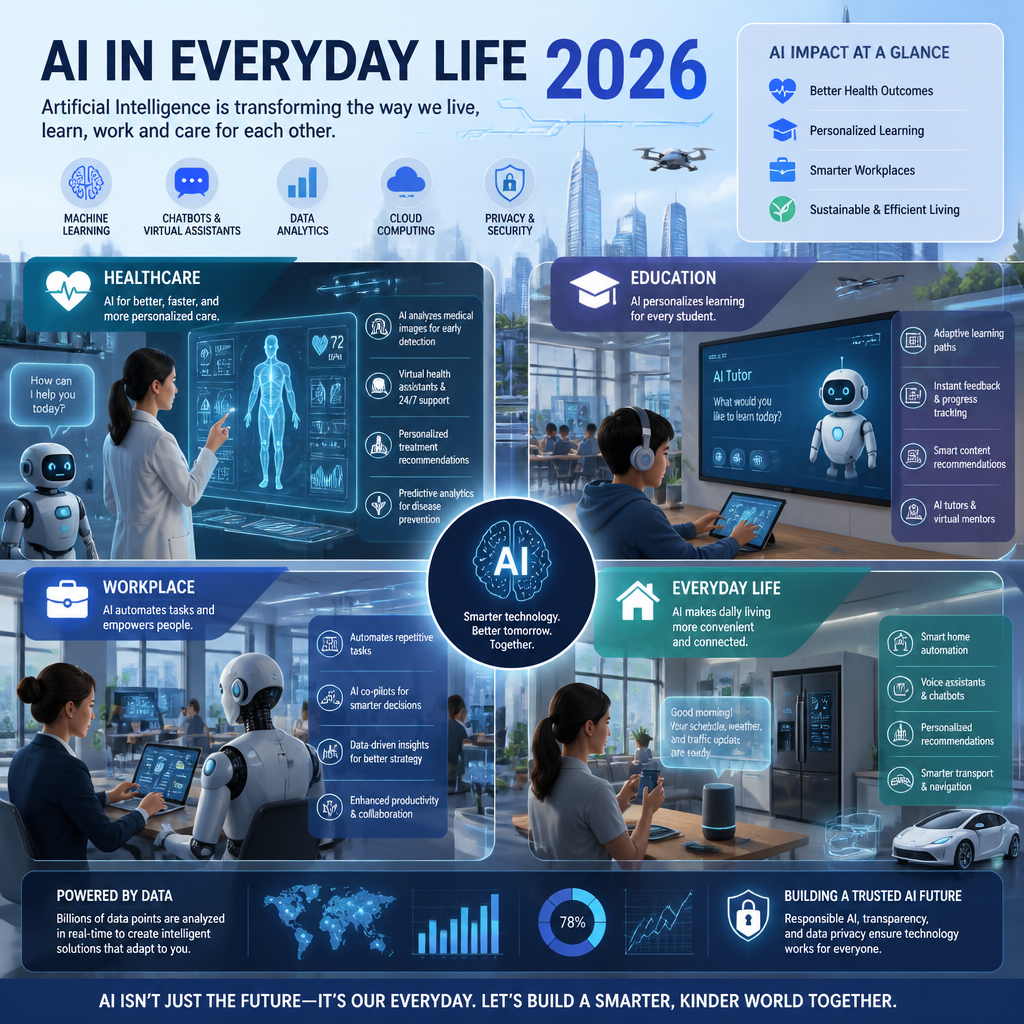
    As we approach 2026, it’s crucial to understand the profound impact artificial intelligence (AI) will have on various aspects of our lives. The change won’t come as one big reveal; instead, it’ll come as a steady drip of features that quietly remove friction.

    In terms of workplace productivity, 44% of U.S. adults believe AI tools increase their productivity (Ipsos). That number matches what I see in the real world: when a team finds a safe, repeatable AI workflow, the “busy work” shrinks fast.

    How AI Works

    At its core, AI mimics human intelligence through algorithms that enable machines to perform tasks that typically require human thinking. This includes learning from experiences (machine learning), understanding natural language, and recognizing patterns (National University). But the part people miss is where the value actually comes from: AI doesn’t “think” like a person—it predicts what’s likely next, based on a lot of examples.

    So, picture your inbox. In 2026, an AI layer won’t just draft replies; it’ll read the thread, notice you’re being asked for a decision, pull the relevant doc link, and propose a short answer in your tone. Meanwhile, it’ll flag two risks: “This customer is asking for a discount you can’t approve,” and “This date conflicts with your existing timeline.” That sounds fancy, but it’s basically pattern recognition plus a clean interface.

    The messy part is reliability. AI works great in the “center” of what it has seen—common tasks, typical phrasing, mainstream situations. But it can get weird on edge cases: unusual legal wording, niche medical history, or your company’s internal acronyms. Because of that, the winning products in 2026 will be the ones that treat AI like a co-pilot with guardrails, not an all-knowing autopilot.

    Another under-discussed piece is latency and cost. If an AI feature takes 12 seconds to respond, people stop using it. If it’s instant, it becomes muscle memory. By 2026, a lot of AI will run in smaller, faster models (sometimes on-device) for speed and privacy, while heavy-duty requests will still go to the cloud.

    AI as a Helpful Tool

    The helpfulness of AI cannot be overstated—if you aim it at the right problems. It’s already making significant strides in sectors like healthcare, where AI-assisted diagnostics are improving patient outcomes. Even outside hospitals, AI is creeping into the “boring” parts: appointment scheduling, symptom checkers that ask better follow-ups, and clinical note drafting.

    A stat that lines up with what teams report: 62% of workers across various countries have reported that AI has saved them time at work (Ipsos). The key phrase there is “saved them time,” not “replaced them.” In practice, the biggest wins come from compressing tiny tasks—rewriting a paragraph, summarizing a call, turning bullet points into a slide, extracting action items from a meeting transcript.

    Here’s a real-feeling example I’ve seen in multiple orgs. A customer support lead starts using AI to draft first responses. At first, it’s clunky, because the AI doesn’t know policy. Then they feed it the help center and a handful of “gold standard” replies, and suddenly new agents ramp in days instead of weeks. Because of that, escalation volume drops, managers get fewer pings, and customers get answers faster. Nobody’s job disappears overnight, but the workflow changes.

    Education will get the same treatment. In 2026, AI-powered tutoring won’t just answer questions; it’ll watch where a student hesitates, then adjust the next explanation. It’ll also give teachers something they rarely get today: a quick map of who’s stuck, on what concept, and since when.

    That said, helpful AI also creates new work. Somebody has to verify outputs, handle exceptions, and decide what “good” looks like. If your organization pretends that part is optional, you’ll feel it in mistakes—wrong orders, mixed-up patient notes, or confidently incorrect emails that burn trust.

    Making AI Helpful

    For AI to be truly helpful, we need to ensure it is designed with users in mind. That sounds obvious, but lots of “AI features” ship because they demo well, not because they reduce real pain.

    In professional settings, AI is expected to evolve into collaborative tools that enhance decision-making rather than replace human roles. Practically, that means three things: (1) it has to show its work (where the info came from), (2) it has to be easy to correct, and (3) it must fail gracefully when it doesn’t know.

    Organizations can use AI to sift through data rapidly, providing insights that would be painful for humans to gather alone. For example, a sales ops team can ask, “Which deals slipped this quarter because of security review delays?” and get a ranked list, plus common blockers. Then they can actually fix the process instead of guessing.

    The adoption curve is already visible: 50% of employed Americans have reported seeing AI tools like ChatGPT in their workplaces (Ipsos). By 2026, the differentiator won’t be “do you have AI?” It’ll be whether your workplace has norms around it.

    If you want AI to help instead of harm, I’d start with rules that feel a little boring:

    • Decide what data must never go into AI tools (client PII, unreleased financials, patient details). Put it in writing.
    • Pick two or three approved tools. Otherwise, you’ll get shadow AI everywhere.
    • Require a human owner for every AI-assisted workflow. When something goes sideways—and it will—you need someone accountable.
    • Measure outcomes, not hype. Time saved is good, but error rates and rework matter more.

    One mistake I’ve watched teams make: they roll out an AI writing tool, then they judge success by “how many people used it.” That’s the wrong metric. Usage goes up even if quality goes down, because it’s novel. The better measurement is: did cycle time drop, did customer satisfaction hold, and did editors spend less time cleaning up?

    Understanding Artificial Intelligence

    Understanding artificial intelligence involves demystifying what it can and cannot do. Plenty of people swing between extremes—either AI is a looming threat, or it’s a miracle machine. The truth sits in the middle, and it’s much more practical.

    In 2026, you’ll get the most out of AI if you treat it like a very fast junior assistant: excellent at first drafts and pattern matching, shaky at judgment, and occasionally overconfident.

    What Exactly Is an AI?

    Artificial Intelligence refers to systems that can perform tasks that typically require human intelligence. This includes problem-solving, understanding language, and even emotional recognition. But it helps to split “AI” into buckets, because they behave differently.

    • Generative AI creates text, images, code, audio. It’s great for drafts, summaries, and transformations (turn this messy note into a clean email).
    • Predictive AI scores likelihood (fraud risk, churn risk, demand forecasting). It’s often less flashy, yet it’s where companies quietly make a lot of money.
    • Perception AI identifies things in the world (speech-to-text, object detection, medical imaging).

    Essentially, AI can look like a human brain on the surface, but it operates through statistical and computational processes rather than biology. That difference matters, because it explains why AI can be eloquent and still wrong.

    Also, “emotional recognition” is a loaded claim in the real world. Systems can detect patterns—tone, word choice, facial movement—but that’s not the same as understanding how you feel. If someone sells you AI that “knows” emotions with certainty, be skeptical.

    By 2026, a lot of consumer AI will feel personal because it remembers preferences: how you write, what you buy, what you watch, when you commute. That kind of personalization can be genuinely useful. It can also feel creepy, especially when the data trail isn’t obvious.

    Human Intelligence vs. AI

    While AI is designed to simulate human thought processes, it is fundamentally different from human intelligence. Humans carry context that never appears in the dataset: social nuance, lived experience, ethics, and responsibility.

    Humans possess emotional reasoning, social understanding, and ethical considerations that AI cannot replicate. This distinction is crucial when discussing the limitations of AI. For instance, while AI can provide recommendations based on data patterns, it cannot engage in moral reasoning or empathy (National University).

    Here’s where this lands in daily life.

    If an AI assistant helps a manager write performance feedback, it might produce something “professional-sounding” that’s emotionally tone-deaf. A person has to notice that, soften it, and decide what the employee actually needs to hear. Similarly, if AI suggests a healthcare next step (“follow up in two weeks”), a clinician has to weigh the human reality: the patient’s support system, anxiety, and ability to get back to the clinic.

    In 2026, you’ll also see more AI “agents” that can take actions—book travel, file tickets, reorder supplies. That’s powerful, but it increases the blast radius of mistakes. A chatbot hallucinating a sentence is annoying. An agent sending the wrong email to the wrong client is an incident.

    So, the practical stance I take is this: let AI generate, propose, and summarize. Keep humans on the hook for decisions, approvals, and anything that touches money, health, or legal exposure.

    Performing Tasks with AI

    The tasks AI performs can range from simple operations, like scheduling appointments, to complex processes like fraud detection in banking. The key takeaway isn’t just that AI can perform these tasks—it’s how it changes the cost and speed of doing them.

    AI systems analyze massive amounts of data at speeds faster than any human could. For example, businesses utilizing AI for marketing analysis can personalize advertisements to cater specifically to individual consumers, boosting conversion rates and customer satisfaction (Kanerika). But personalization has tradeoffs: it can narrow what you see, reinforce habits, and make it harder to “browse” outside your usual bubble.

    By 2026, I expect the biggest task-level shifts to show up in five places:

    1. Writing and rewriting everywhere. Not just marketing—HR policies, internal docs, procurement emails, project updates. People who can clearly instruct an AI (“shorter, friendlier, keep the key details, don’t promise timelines”) will look like better communicators.
    2. Meetings get compressed. AI will auto-generate agendas, capture decisions, and assign tasks. The win isn’t the transcript; it’s fewer follow-up meetings because the next steps are actually written down.
    3. Customer support triage. AI will route tickets, detect urgency, and propose replies based on policy. Good teams will keep a human QA loop and track when AI suggestions get edited—those edits become training data.
    4. Front-line data cleanup. The unglamorous stuff: matching duplicate records, fixing address formats, tagging documents, extracting fields from PDFs. This is where time disappears today, so it’s where AI can give it back.
    5. Personal life logistics. Meal planning with your dietary constraints, shopping lists that adapt to your budget, travel planning that accounts for layovers you hate. Helpful when it works; frustrating when it doesn’t.

    One more mini story, because it’s the kind of thing that’s about to be normal. A friend of mine runs a small professional services firm. They used to spend Sunday nights assembling weekly client updates—status, blockers, next steps. After adding an AI step that summarizes work logs and drafts the email, the owner now spends 20 minutes editing instead of two hours writing. Because of that, they do the update every week, not “when things are on fire.” The client experience improves, and the team gets fewer random check-in calls.

    None of this removes the need for human taste. If you don’t know what a good client update looks like, AI won’t save you. It’ll just produce a longer bad update.

    In conclusion, as we move toward 2026, AI will play an increasingly critical role in our lives. It will help us be more productive, enhance decision-making, and lead to new opportunities across various sectors.

    Still, the expectation shouldn’t be that AI makes everything better by default. The teams and individuals who win will be the ones who set boundaries, learn how to prompt and review, and keep humans responsible for the high-stakes calls. If you want a next step: pick one repetitive task you do weekly, run it through an AI assistant for two weeks, and track time saved and mistakes—then decide if it deserves a permanent place in your workflow.

  • How AI Will Change Our Lives in 2026

    How AI Will Change Our Lives in 2026

    Discover how AI will change our lives by 2026. Learn about key trends, applications, and the future of technology in everyday life.

    Featured image for How AI Will Change Our Lives in 2026

    How AI Will Change Our Lives in 2026

    By 2026, AI won’t feel “special.” It’ll feel like Wi‑Fi: you only notice it when it’s missing, wrong, or expensive. Meanwhile, the best implementations will quietly remove friction—drafting, summarizing, routing requests, catching anomalies, and predicting outcomes.

    The 2026 AI Index Report frames 2026 as a point where AI capability and adoption collide: more usable models, more deployment, more measurable productivity impact. I buy that, but with a caveat—most of the value will come from boring integration work, not model magic.

    How AI will change our lives in 2026 – AI assistants embedded in everyday apps

    How AI Works

    AI “works” because it learns patterns from data, then applies those patterns to new inputs. That sounds obvious, but the messy part is that patterns aren’t understanding. So, AI can look smart while still being wrong in surprisingly confident ways.

    Here’s the practical breakdown I use when explaining AI systems to non-ML teammates:

    1. You collect inputs (customer chats, documents, transaction logs, images, sensor readings). But you also decide what not to collect—because privacy and cost are real constraints.
    2. You clean and shape the data so the system can learn from it. This step is where most timelines slip, since teams underestimate edge cases.
    3. A model trains or gets selected (sometimes you fine-tune, often you don’t). Then you measure basic metrics—accuracy, latency, cost per request.
    4. You wrap it in a product workflow (approvals, fallbacks, guardrails, human-in-the-loop). Without this, AI stays a toy.
    5. You monitor drift and failure modes because inputs change. Users change. The business changes. AI systems need babysitting.

    That last point is why “set it and forget it” AI usually turns into a quiet incident later. I’ve seen a support bot get steadily worse over six weeks simply because the product UI changed and customers started describing the same actions with new words.

    What Exactly is an AI?

    An AI (artificial intelligence) is software that imitates parts of intelligent human behavior—recognizing patterns, generating text, making predictions, and choosing actions inside a defined environment. The key phrase there is defined environment.

    The What is an AI Overview article gets at an important reality: modern AI systems don’t just “retrieve information.” They generate responses that sound contextually relevant, which means they can be helpful and misleading in the same breath.

    So, in practice, I separate AI into two buckets:

    • Predictive AI: “Given history, what happens next?” (fraud detection, demand forecasting, medical risk scoring).
    • Generative AI: “Given a prompt, produce content.” (draft emails, code suggestions, summaries, designs).

    Both are useful, but generative AI is where people get sloppy, because it produces fluent output. Fluency is not correctness.

    Artificial Intelligence in Daily Life

    In daily life, AI will show up less as “a chatbot” and more as invisible decisions being made for you—sometimes correctly, sometimes not.

    A few places you’ll feel it by 2026:

    • Personal health: apps that flag sleep, heart rate anomalies, nutrition gaps, and then nudge you. Helpful, but you’ll need to understand when it’s guessing.
    • Smart homes: devices that learn routines and optimize energy use. Convenient, although misconfigured automation can be a security headache.
    • Education: tutoring and feedback loops that adjust in real time. Great for practice, but it can also create dependency if students never learn to reason without prompts.
    • Payments and banking: more real-time fraud controls and personalized financial advice. The tradeoff is more false positives—your card gets blocked “for your safety.”

    A real example: I watched a friend’s elderly parent get locked out of online banking for two days after an “unusual pattern” alert. AI did its job, but the bank’s escalation path was slow, so the human cost was high. That’s the theme—AI’s decisions are only as good as the human process around them.

    Google AI and Its Transformations

    Google AI is already reshaping how people find answers. AI Overviews change the search journey because users can get a synthesized response without clicking through multiple sources.

    Google explains this direction in their documentation on AI Overviews as part of the Search Generative Experience. That shift matters for two reasons:

    • For users: faster “good enough” answers, less time digging.
    • For publishers and businesses: fewer clicks, more pressure to be the cited source (and to build brands people seek out directly).

    If you run a site, a store, or even an internal knowledge base, you’ll need to adapt. You can’t just publish generic content and hope SEO carries you. You’ll have to earn trust, show firsthand experience, and write the kind of material AI systems want to reference.

    Future Job Implications: Which Roles Will Remain?

    AI will automate tasks, not entire humans—at least at first. Still, if your job is mostly “moving information from one place to another,” expect pressure.

    Roles that tend to hold up better:

    • High-context communication: therapists, negotiators, senior account managers.
    • Hands-on physical work: trades, repair, clinical procedures, field operations.
    • Creative direction: not “make a logo,” but “decide what the brand should feel like and why.”
    • Accountability-heavy roles: compliance owners, safety leads, people who sign off.

    People also worry about the environmental costs of AI, and that concern is fair. At the same time, adoption keeps climbing. One data point that sticks with me: 49% of people believe AI’s potential benefits for society outweigh the environmental costs (Ipsos). That doesn’t make the tradeoff disappear, but it does explain why organizations keep pushing forward.

    Understanding AI Technology

    If you want to make sane decisions about AI in 2026, you need a working mental model—capabilities, limits, and what usually goes wrong. Otherwise, you’ll either overtrust it or dismiss it, and both are expensive mistakes.

    Making AI Helpful

    “Helpful AI” isn’t about a clever prompt. It’s about designing a system that behaves predictably inside a real workflow.

    When we embed AI into a product or internal tool, I think in layers:

    1. Define the job: one narrow outcome (summarize a ticket, classify a lead, draft a reply). If you start with “do everything,” you’ll ship nothing.
    2. Decide the acceptable error: is 90% correct okay, or does one mistake create legal risk? This single decision changes the whole architecture.
    3. Add guardrails: banned actions, red-flag topics, citations, and “I don’t know” behaviors. Without guardrails, the model improvises.
    4. Build a fallback: if AI confidence is low, route to a human or to a deterministic rule engine.
    5. Instrument it: track cost per task, time saved, correction rate, and user satisfaction.

    A common mistake: teams obsess over model choice and ignore workflow fit. I’ve seen an AI assistant generate gorgeous responses that agents still had to rewrite because the company’s tone, policies, and refund rules weren’t encoded anywhere.

    This is also where platforms like mobeen-workspace matter—owning your stack, controlling your integrations, and putting AI inside your governance, not the other way around. If you can’t audit inputs/outputs and control access, you’re building on sand.

    AI in Business

    Businesses adopt AI for three reasons: reduce cost, increase throughput, or unlock something they couldn’t do before (like real-time personalization). The best projects start with one of those and measure it.

    The IBM 2026 CEO Study points to AI as a major driver for executing strategy and delivering consistent results. That matches what I see: companies that operationalize AI—meaning they integrate it into repeatable processes—tend to outperform the ones that only experiment.

    Here’s a step-by-step rollout plan I’ve used that doesn’t implode:

    • Week 1–2: Pick a single workflow (support triage, invoice extraction, lead qualification). Tie it to a KPI.
    • Week 3–4: Build a small pilot with real data, plus basic logging. Don’t hide the AI; label it.
    • Week 5–6: Add human-in-the-loop for the risky parts (approvals, escalations). Measure edits.
    • Week 7–8: Harden it (rate limits, permissions, prompt injection defenses, retries, fallbacks).
    • Month 3: Decide: scale, pause, or kill. Killing is a win if you learned cheaply.

    Most failed AI initiatives skip the “kill decision.” They drift into production half-supported, then everyone quietly hates them.

    The Future of AI

    By 2026, the conversation will shift from “Can AI do this?” to “Should we let it?” and “Who’s accountable when it fails?” Capability will keep rising, but so will the blast radius.

    A few changes I expect to be mainstream:

    • More on-device or hybrid AI for privacy and latency (especially health and personal assistants).
    • Stronger demand for provenance: where did this answer come from, and can I verify it?
    • AI governance as normal ops: approvals, audits, retention policies, incident response.

    The 2026 AI Index Report is useful here because it tracks the growth curve and adoption pressure. Still, the organizations that win won’t be the ones with the fanciest demos. They’ll be the ones with disciplined processes—testing, monitoring, and clear ownership.

    Conclusion

    AI will change our lives in 2026, but not because every app becomes a robot. It’ll change life because decision-making, content creation, and routine work will get partially automated everywhere.

    If you treat AI like a junior teammate—fast, sometimes brilliant, occasionally wrong, always needing oversight—you’ll get the upside without wrecking trust. Build the guardrails now, because cleaning up later costs more.

    My Experience With This

    I’m Mobeen Abdullah, Founder & CEO of Revnix, and I’ve spent over a decade building cloud-native systems and AI platforms that have to run in the real world—deadlines, constraints, and users who don’t care about your architecture diagrams.

    One of the earliest lessons I learned: AI projects fail less from “bad models” and more from bad plumbing. You can have a strong model and still ship a useless product if you don’t handle permissions, logging, data quality, and feedback loops.

    Here’s a real pattern I’ve seen with clients and internal builds. Someone says, “Let’s add an AI assistant to support.” The first prototype looks amazing because it’s tested on clean examples. Then production hits:

    • Customers paste screenshots, broken English, and half a story.
    • Internal policy docs contradict each other.
    • Edge cases show up (refund exceptions, compliance rules, regional constraints).

    So we fix it the hard way—by tightening scope and adding controls. We’ll start with triage (classify issue, suggest category, pull relevant policy snippets), not full auto-replies. Then, once we can measure correction rates and reduce handle time, we expand.

    The most painful mistake I’ve watched teams make is letting AI speak “as the company” too early. If it hallucinates a policy, you don’t just lose accuracy—you lose trust. After you lose trust, adoption dies, and then leadership blames “AI” instead of the rushed rollout.

    What I’m biased toward is boring reliability: narrow tasks, measurable impact, and auditability. If you want a next step, pick one workflow you touch weekly, write down what “better” means (minutes saved, fewer errors, faster response), and pilot AI there with a human backstop. That’s how you get real progress without betting the house.